

Setup guide
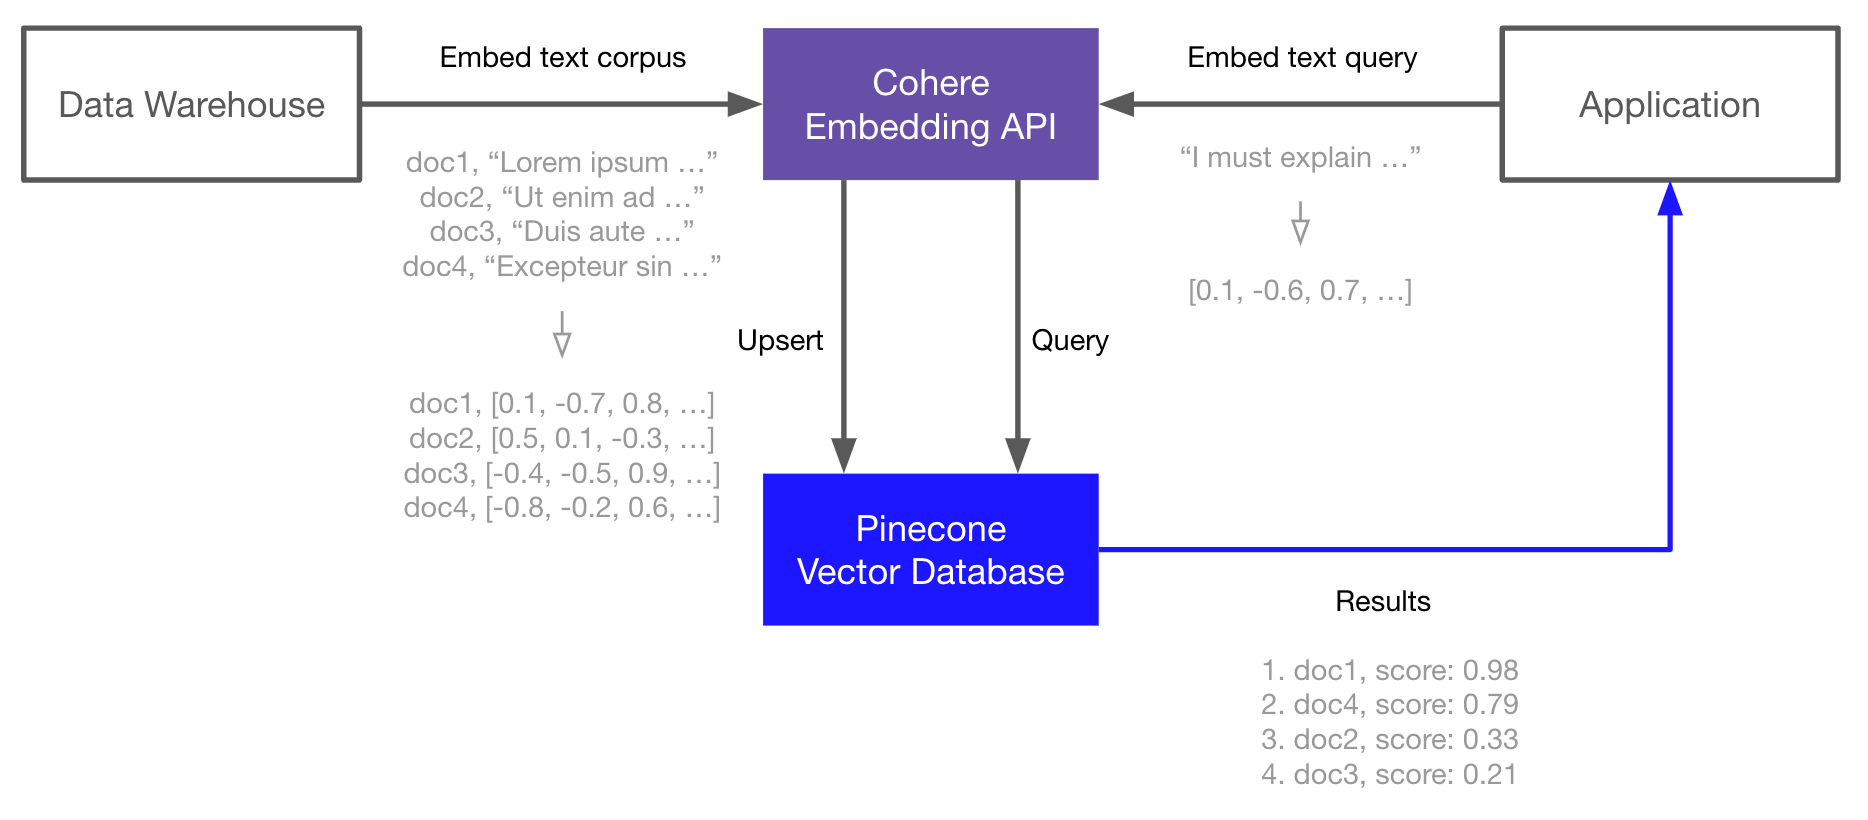
In this guide, you’ll learn how to use the Cohere Embed API endpoint to generate language embeddings, and then index those embeddings in Pinecone Database for fast and scalable vector search. This is a common combination for building semantic search, question-answering, threat-detection, and other applications that rely on NLP and search over a large corpus of text data. The basic workflow looks like this:- Embed and index
- Use the Cohere Embed API endpoint to generate vector embeddings of your documents (or any text data).
- Upload those vector embeddings into Pinecone, which can store and index millions or billions of these vector embeddings and search through them at low latency.
- Search
- Pass your query text or document through the Cohere Embed API endpoint again.
- Take the resulting vector embedding and send it as a query to Pinecone.
- Get back semantically similar documents, even if they don’t share any keywords with the query.
Set up the environment
Start by installing the Cohere and Pinecone clients, along with Hugging Face Datasets for downloading the TREC dataset used in this guide:
Shell
Create embeddings
Sign up for an API key at Cohere and then use it to initialize your connection.Load the Text REtrieval Conference (TREC) question classification dataset, which contains 5.5K labeled questions. You’ll take only the first 1K samples for this walkthrough, but you can scale this to millions or even billions of samples.Each sample in Check the dimensionality of the returned vectors. Save the embedding dimensionality, because you need it when you create your Pinecone index later.You can see the
Python
Python
trec contains two label features and the text feature. Pass the questions from the text feature to Cohere to create embeddings. The Embed API accepts up to 96 texts per request, so send them in batches.Python
Python
Response
1024 embedding dimensionality produced by Cohere’s embed-english-v3.0 model, and the 1000 samples you built embeddings for.Store the embeddings
Now that you have your embeddings, you can move on to indexing them in Pinecone Database. For this, you need a Pinecone API key.First, initialize your connection to Pinecone, and then create a new index called Now you can begin populating the index with your embeddings. Pinecone expects you to provide a list of tuples in the format You can see from
cohere-pinecone-trec for storing the embeddings. When you create the index, specify the cosine similarity metric to align with Cohere’s embeddings, and pass the embedding dimensionality of 1024.Python
(id, vector, metadata), where the metadata field is an optional extra field where you can store anything you want in a dictionary format. For this example, you’ll store the original text of the embeddings.Upload the data in batches to avoid pushing too much data at once.Python
Response
index.describe_index_stats that you have a 1024-dimensional index populated with 1000 embeddings.Run a semantic search
Now that you have your indexed vectors, you can perform a few search queries. To search, first embed your query with Cohere, and then search Pinecone with the returned vector.The response from Pinecone includes your original text in the The top results are relevant. To make the search harder, replace “depression” with the incorrect term “recession.”Finally, search using the definition of depression rather than the word or related words.This example shows that the semantic search pipeline can identify the meaning behind each of your queries. Using these embeddings with Pinecone lets you return the most semantically similar questions from the already indexed TREC dataset.
Python
metadata field. Print the top_k most similar questions and their similarity scores.Python
Response
Python
Response
Python
Response