

Setup guide
This guide shows how to integrate OpenAI’s LLMs with Pinecone, a combination referred to as the OP stack. LLMs like OpenAI’stext-embedding-3-small generate vector embeddings, i.e., numerical representations of text semantics. These embeddings enable semantic matches rather than literal text matches. Additionally, LLMs like gpt-4o-mini can predict text completions based on information provided from these contexts.
Pinecone Database stores and queries high-dimensional vectors and provides fast semantic search over them.
There are many ways to integrate these two tools, and Pinecone has several guides that focus on specific use cases. If you already know what you’d like to do, start with one of these:
Introduction to embeddings
At the core of the OP stack are embeddings, which come from the OpenAI Embedding API. You index those embeddings in Pinecone Database for fast, scalable retrieval augmentation of your LLMs and other information retrieval use cases. This example demonstrates the core OP stack. It’s the simplest workflow and is present in each of the other workflows, but it isn’t the only way to use the stack. For more advanced usage, see the guides listed earlier. The OP stack is built for semantic search, question-answering, threat-detection, and other applications that rely on language models and a large corpus of text data. The basic workflow looks like this:- Embed and index
- Use the OpenAI Embedding API to generate vector embeddings of your documents (or any text data).
- Upload those vector embeddings into Pinecone, which can store and index millions or billions of these vector embeddings and search through them at low latency.
- Search
- Pass your query text or document through the OpenAI Embedding API again.
- Take the resulting vector embedding and send it as a query to Pinecone.
- Get back semantically similar documents, even if they don’t share any keywords with the query.
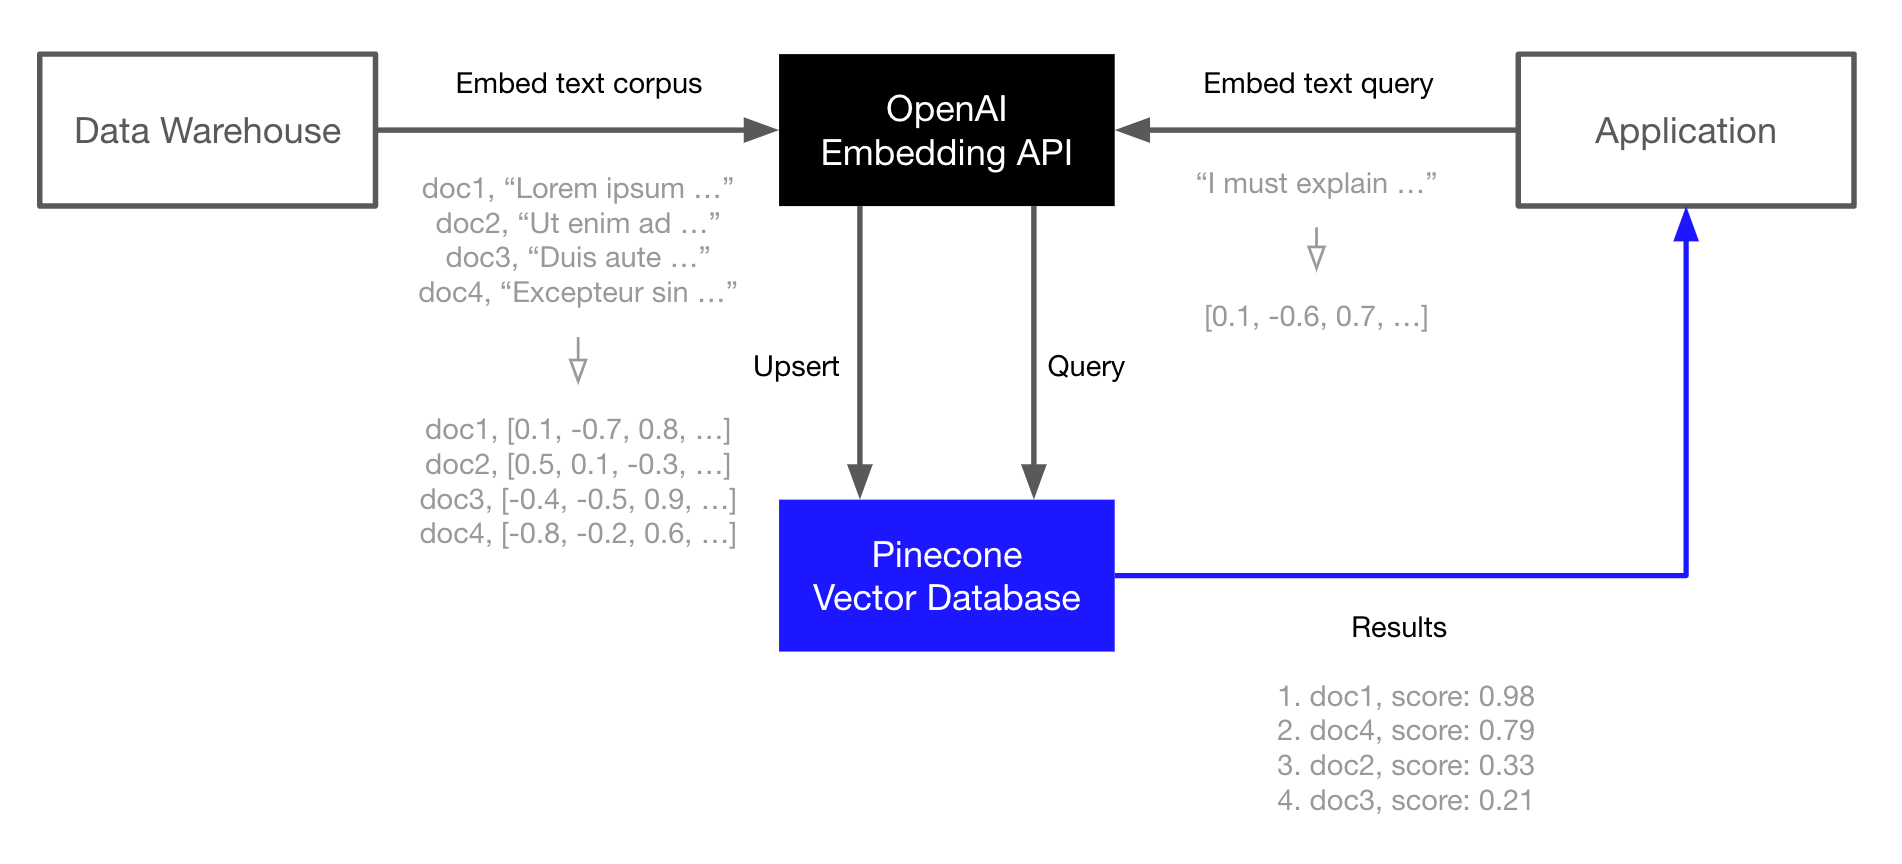
Set up the environment
Start by installing the OpenAI and Pinecone clients, along with Hugging Face Datasets for downloading the TREC dataset used in this guide.
Shell
Create embeddings
To create embeddings, first initialize your connection to OpenAI. Sign up for an API key at OpenAI.You can now create embeddings with the OpenAI v3 small embedding model.In You’ll use this logic later when you create embeddings for the Text REtrieval Conference (TREC) question classification dataset.
Python
Python
res, you should find a JSON-like object containing two 1536-dimensional embeddings. These are the vector representations of the two inputs. To access the embeddings directly, extract them to a list.Python
Create an index
Next, initialize an index to store the vector embeddings. For this, you need a Pinecone API key. Sign up for one.
Python
Store the embeddings
With both OpenAI and Pinecone connections initialized, you can populate the index. For this, you need the TREC dataset.Then create a vector embedding for each question using OpenAI (as demonstrated earlier), and
Python
upsert the ID, vector embedding, and original text for each phrase to Pinecone.Python
Run a semantic search
With your data indexed, you’re ready to perform searches. This follows a similar process to indexing. Start with a text Now query the index.The response from Pinecone includes your original text in the The top results are relevant. To make the search harder, replace “depression” with the incorrect term “recession.”Finally, search using the definition of depression rather than the word or related words.This example shows that the semantic search pipeline can identify the meaning behind each of your queries. Using these embeddings with Pinecone lets you return the most semantically similar questions from the already indexed TREC dataset.
query that you want to use to find similar sentences. As before, encode it with text-embedding-3-small to create a query vector, xq. Then use xq to query the Pinecone index.Python
Python
metadata field. Print the top_k most similar questions and their similarity scores.Python
Response
Python
Response
Python
Response